On this page
llms.txt is one of the most recommended AI search fixes of 2026, and one of the least used by the crawlers it is written for. That is not an opinion. It shows up in server logs.
This guide covers what the file is, what the evidence says, and where it belongs on a sensible to-do list.
What llms.txt is
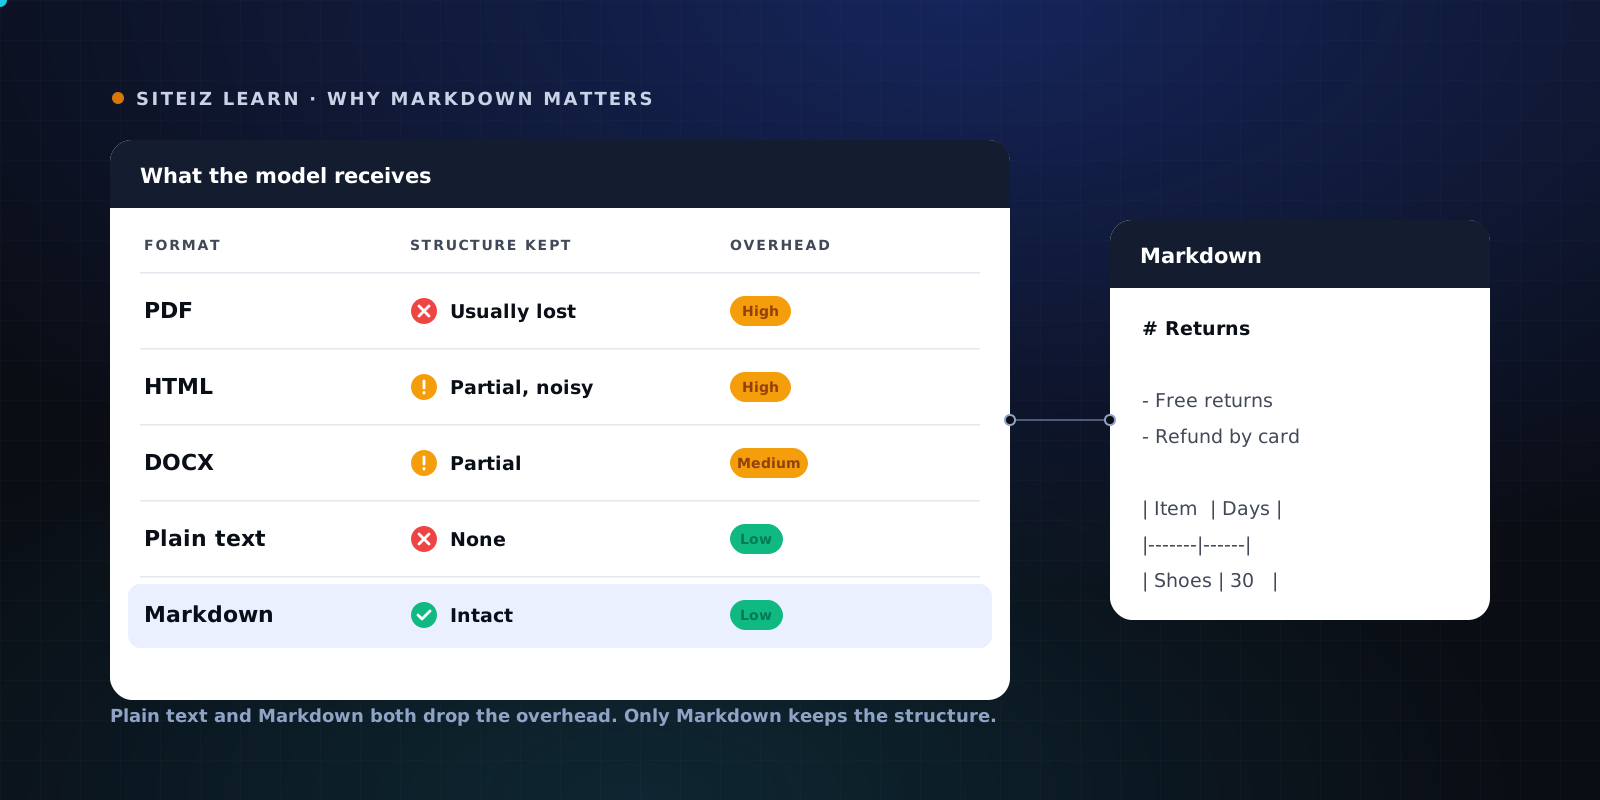
An llms.txt file is a Markdown document at the root of your domain, at /llms.txt. It gives a short description of your site and a curated list of links to the pages that matter most, often pointing at clean Markdown versions of those pages. The idea, proposed in 2024, is that a language model can read one small file instead of crawling a heavy site.
A minimal one looks like this:
# Acme Analytics

> Product analytics for B2B SaaS teams. Plans from 49 EUR per month.

## Product
- [Pricing](https://acme.example/pricing): plans, limits and what each includes
- [Integrations](https://acme.example/integrations): supported data sources

## Docs
- [Getting started](https://acme.example/docs/start): set up tracking in ten minutes
It is not a standard. No major AI company has said it reads the file.
What the server logs show
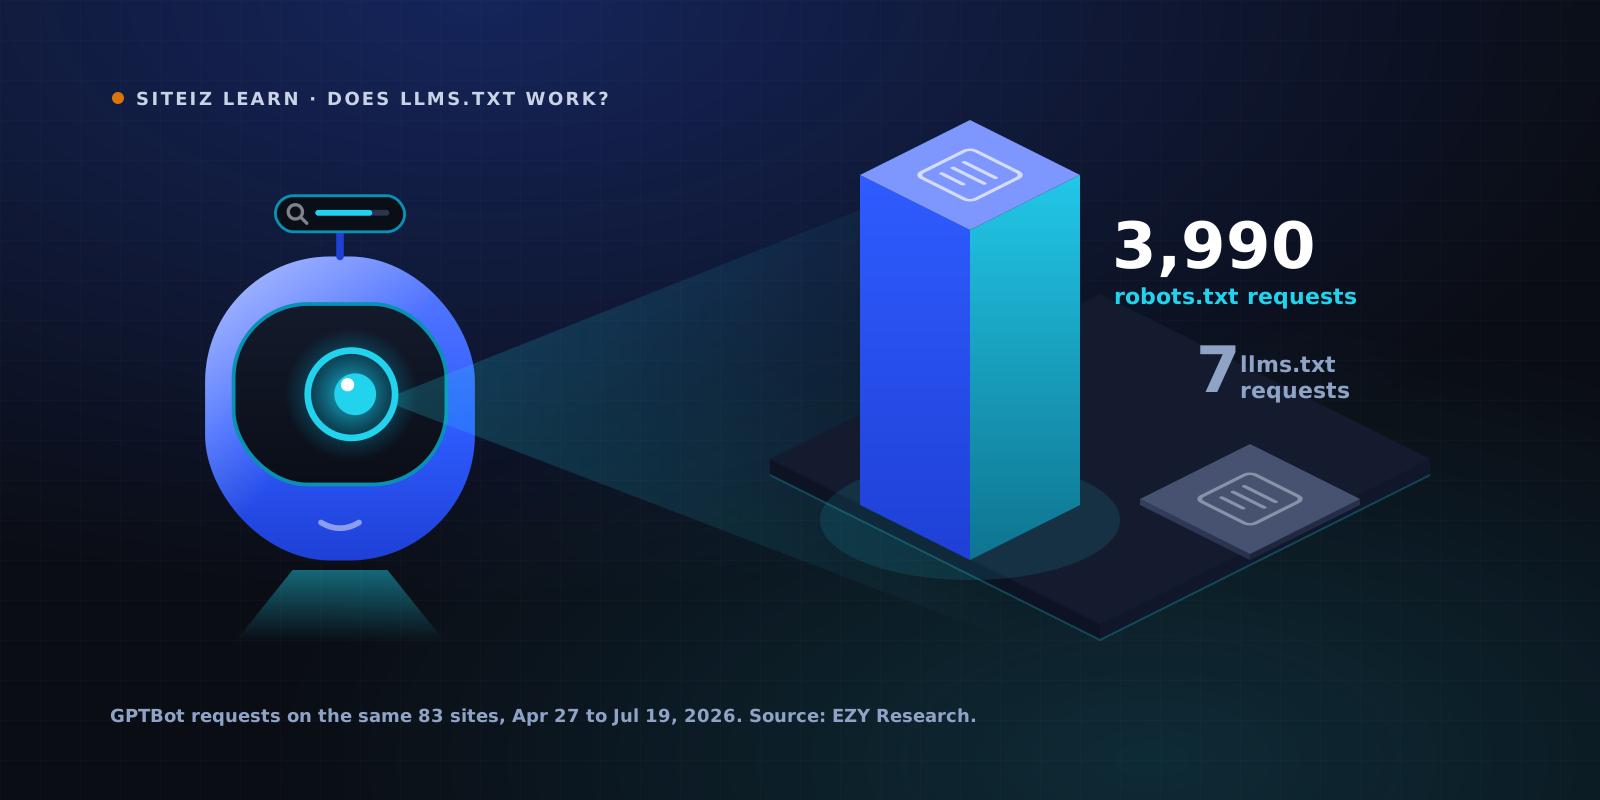
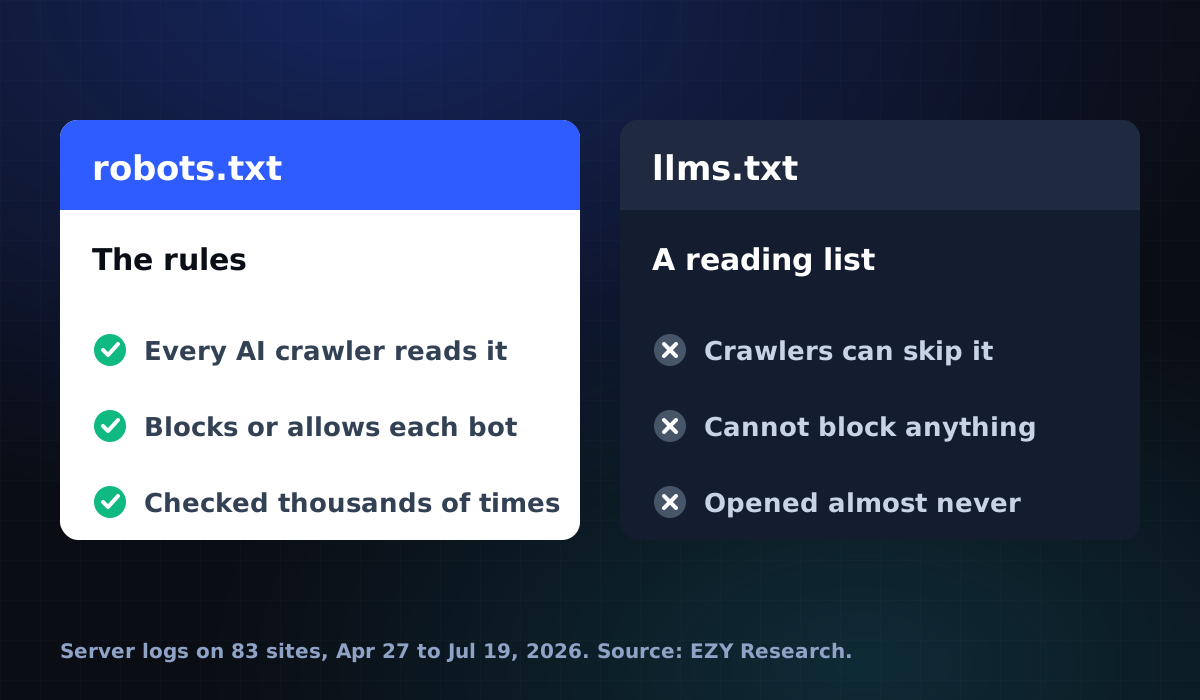
The cleanest public test so far: EZY Research placed a valid llms.txt on 83 real sites and logged every request from named AI crawlers between April 27 and July 19, 2026. It compared llms.txt requests with robots.txt requests on the same domains.
| Crawler | llms.txt requests | robots.txt requests |
|---|---|---|
| GPTBot (OpenAI) | 7 | 3,990 |
| ClaudeBot (Anthropic) | 9 | 3,120 |
| PerplexityBot | 0 | 775 |
| Meta's crawler | 193 | 172 |
The crawlers behind ChatGPT, Claude and Perplexity checked robots.txt thousands of times. They opened llms.txt almost never and went straight to the HTML.
Meta's crawler is the one exception. At least one lab reads the file. That does not mean the others will follow.
What Google says
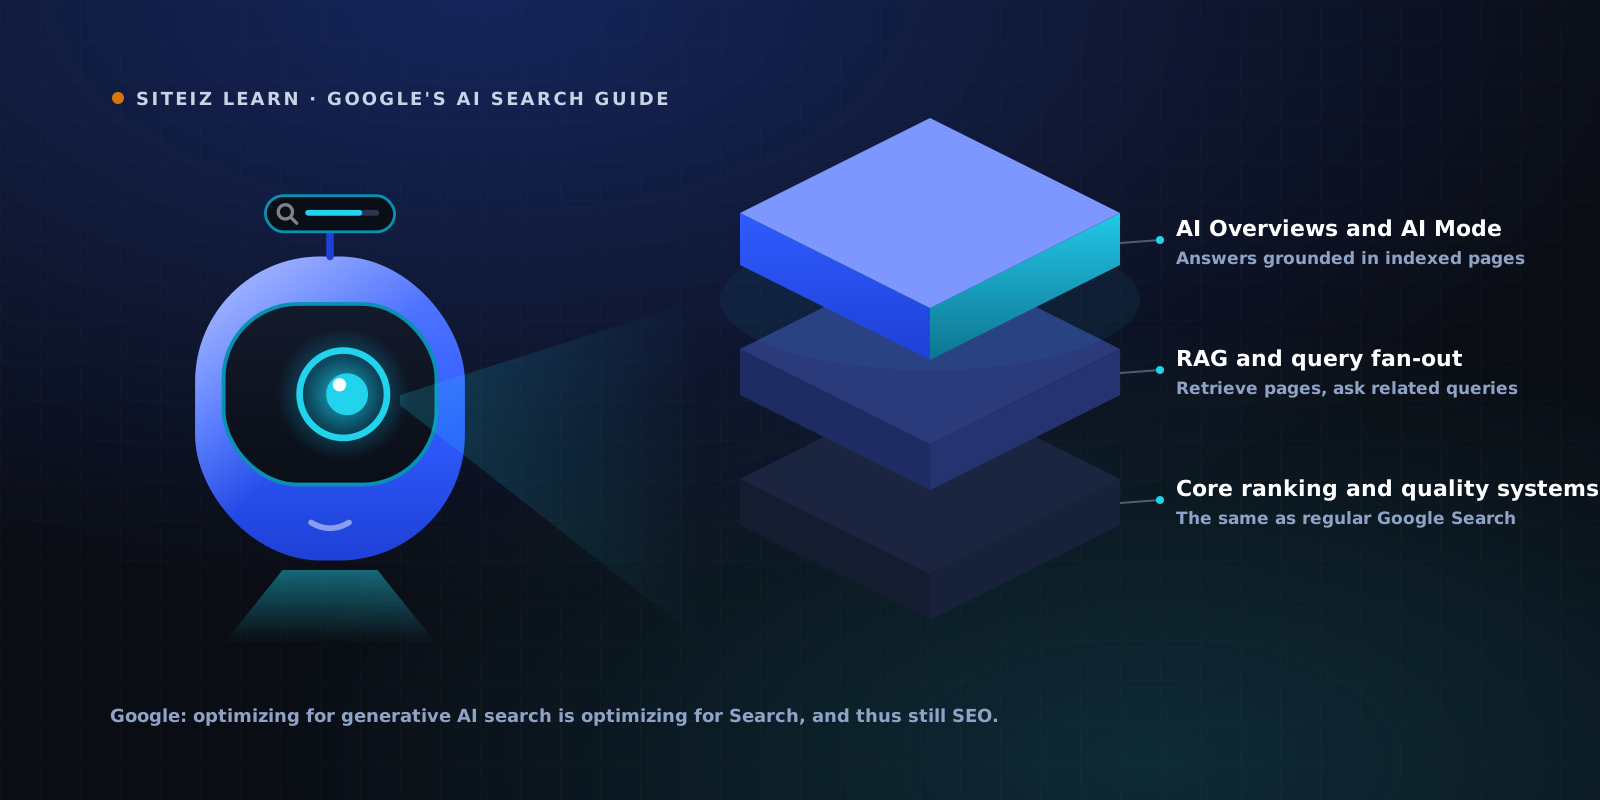
Google settled its own position in its guide to optimizing for generative AI features, published May 15, 2026 and updated July 10. It says you do not need to create "machine readable files, AI text files, markup, or Markdown" to appear in Google Search, including AI Overviews and AI Mode, because Google Search itself does not use them. It adds that keeping an llms.txt for other services will neither help nor harm your Google visibility. Google may crawl the file like any other URL, without treating it in a special way.
Google is not fully consistent here. Chrome's Lighthouse has an experimental Agentic Browsing audit that looks at llms.txt. That audit is about browser agents completing tasks, not Search rankings, so both statements can be true at once. For Google Search, the file does nothing. Our breakdown of what Google's AI search guide rules out covers the rest of the list.
Why it keeps getting recommended
Three reasons, none of them evidence of impact.
- It is easy to sell. A file is a deliverable you can point at. Fixing server rendering is not.
- Tools flag it. Some SEO tools now report a missing llms.txt as an issue, which makes it feel required.
- One fetch gets read as a trend. A single request in a log file is an anecdote. The study above counted every request for twelve weeks.
When llms.txt still makes sense
Cheap is not the same as useless. Add one if:
- Your buyers are developers. Coding assistants and agent frameworks sometimes look for llms.txt to find documentation quickly.
- You already have clean Markdown versions of key pages, so the file costs minutes and points at something useful.
- You want a curated map of your most important pages. Writing it is a useful exercise even if no crawler reads the result.
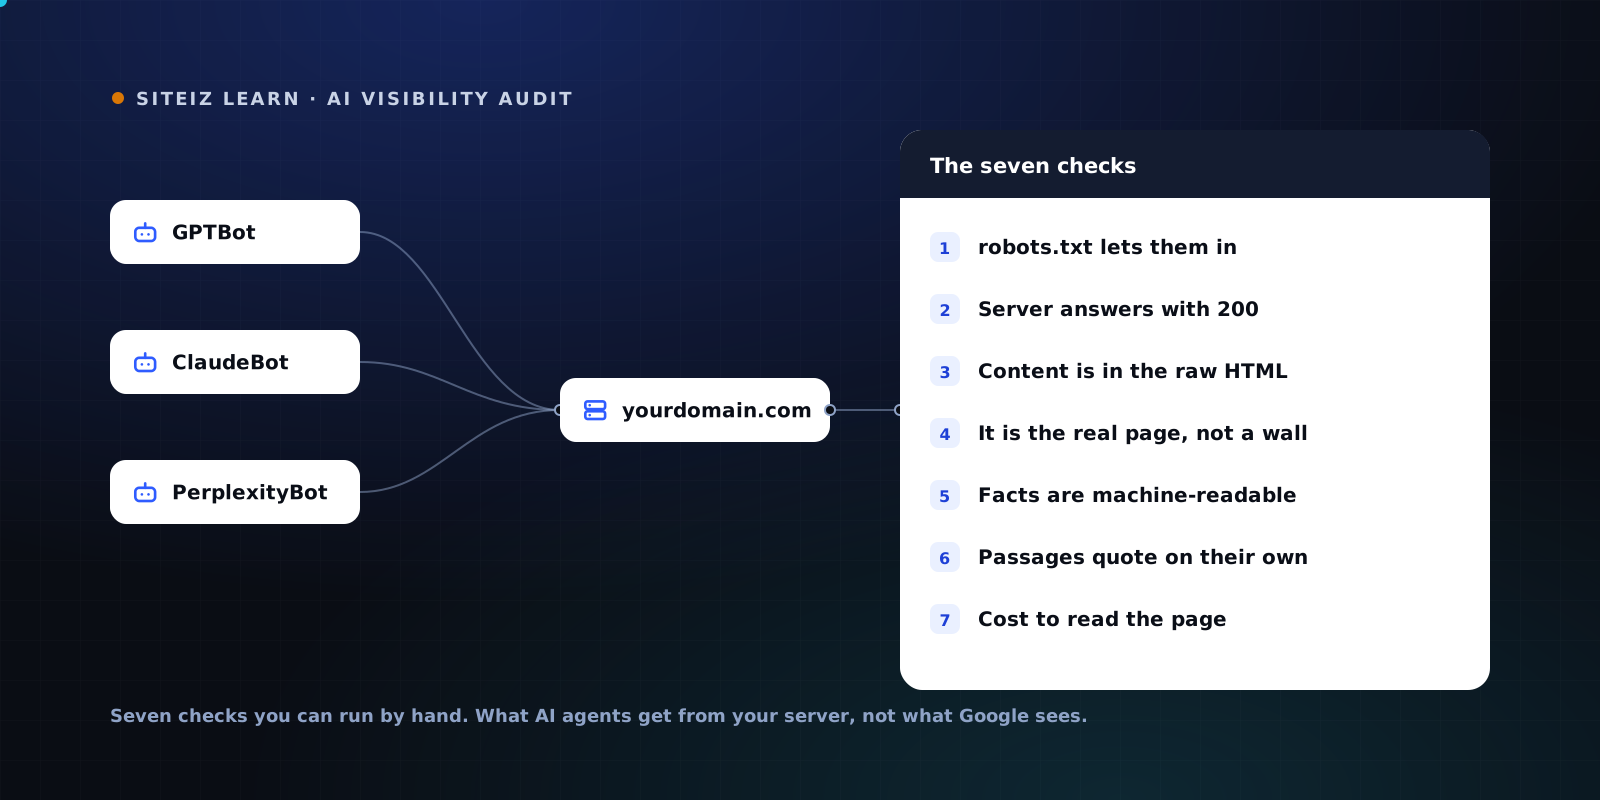
Do not add one instead of the fixes that matter. Work in this order:
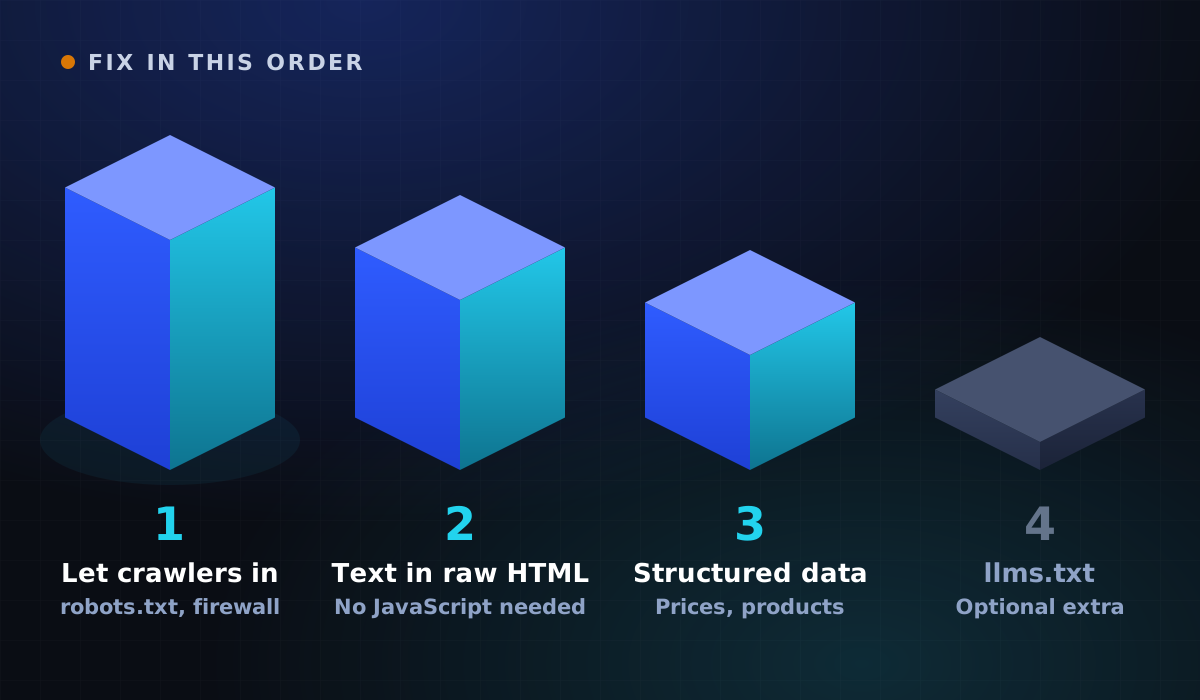
The AI visibility audit walks through each check with the commands to run.
Check whether crawlers fetch yours
You do not need to trust anyone's study. Your own logs will tell you.
BOTS="gptbot|claudebot|perplexitybot|oai-searchbot|meta-externalagent"
grep "/llms.txt" access.log | grep -Eic "$BOTS"
grep "/robots.txt" access.log | grep -Eic "$BOTS"
Compare the two counts over a month. If the first is near zero while the second runs into the hundreds, your llms.txt is being skipped like everyone else's. On Cloudflare or Vercel, filter the request logs by path and user agent for the same answer.
What it means for your website
Our scan checks those three things. It does not score llms.txt, because the evidence does not support it, as the scoring method explains.
See what AI crawlers actually receive from your page with the free Siteiz scan.
FAQ
Common questions
Short answers to what people ask most about this topic.
Does ChatGPT read llms.txt?
Rarely, as far as public logs show. In EZY Research's study of 83 sites between April 27 and July 19, 2026, GPTBot requested llms.txt 7 times against 3,990 requests for robots.txt on the same domains. OpenAI has not said it uses the file.
Does Google use llms.txt for AI Overviews or AI Mode?
No. Google's guide to generative AI features in Search, last updated July 10, 2026, says Google Search does not use llms.txt or other AI text files, so the file neither helps nor harms your visibility there.
Should I still create an llms.txt file?
If it takes you under an hour to make and keep current, it does no harm, and some agents and developer tools do read it. Treat it as a convenience file, not a visibility lever, and never let it replace fixing crawler access or JavaScript-only content.
Is llms.txt the same as robots.txt?
No. robots.txt tells crawlers what they may fetch, and every major AI crawler checks it. llms.txt only suggests what to read, and nothing obliges a crawler to open it.