AI readiness report · Software and cloud
Microsoft AI visibility report
Real scan of microsoft.com · · one page, the homepage
Microsoft's homepage scores 65 out of 100 (grade C) for AI readiness. Its strongest area is crawl access (100), and the biggest drag is citability (10). The single most valuable fix, "serve your full content in the initial html", is worth about 10 points on its own.
Hidden from AI crawlers
10%
of the text people see only appears after JavaScript runs
Reading cost
65×
~65,316 tokens of HTML for ~1,010 tokens of content
Structured data
0
valid schema.org entities in the raw HTML
AI crawlers blocked
0 of 11
named AI agents shut out by robots.txt for this page
Six pillars
Where the points go
Each pillar is scored 0 to 100 by fixed rules and weighted into the total. How scoring works
What we found
What we would change first
- CriticalCitability-90 pts
0 citable facts found in the raw HTML. LLMs cannot cite what isn't in the source.
0 numbers, prices, dates, measurements or certifications detected in the raw text
- CriticalToken economics-66 pts
Reading this page costs an agent ~65,316 tokens for ~1,010 tokens of actual content, a ~65× cost multiplier (98% markup, scripts, and boilerplate).
~65,316 raw tokens vs ~1,010 content tokens, ~65× cost multiplier
- CriticalActionability-20 pts
11 distinct call(s)-to-action exist only in the JS-rendered DOM, absent from the raw HTML, so agents working from the source are likely to miss them.
"accept", "reject", "manage cookies", "no, thanks", "more"
- CriticalVisibility-12 pts
3 heading(s) shown to humans are missing from the raw HTML, they exist only after JavaScript rendering, so crawlers that skip rendering are likely to miss them.
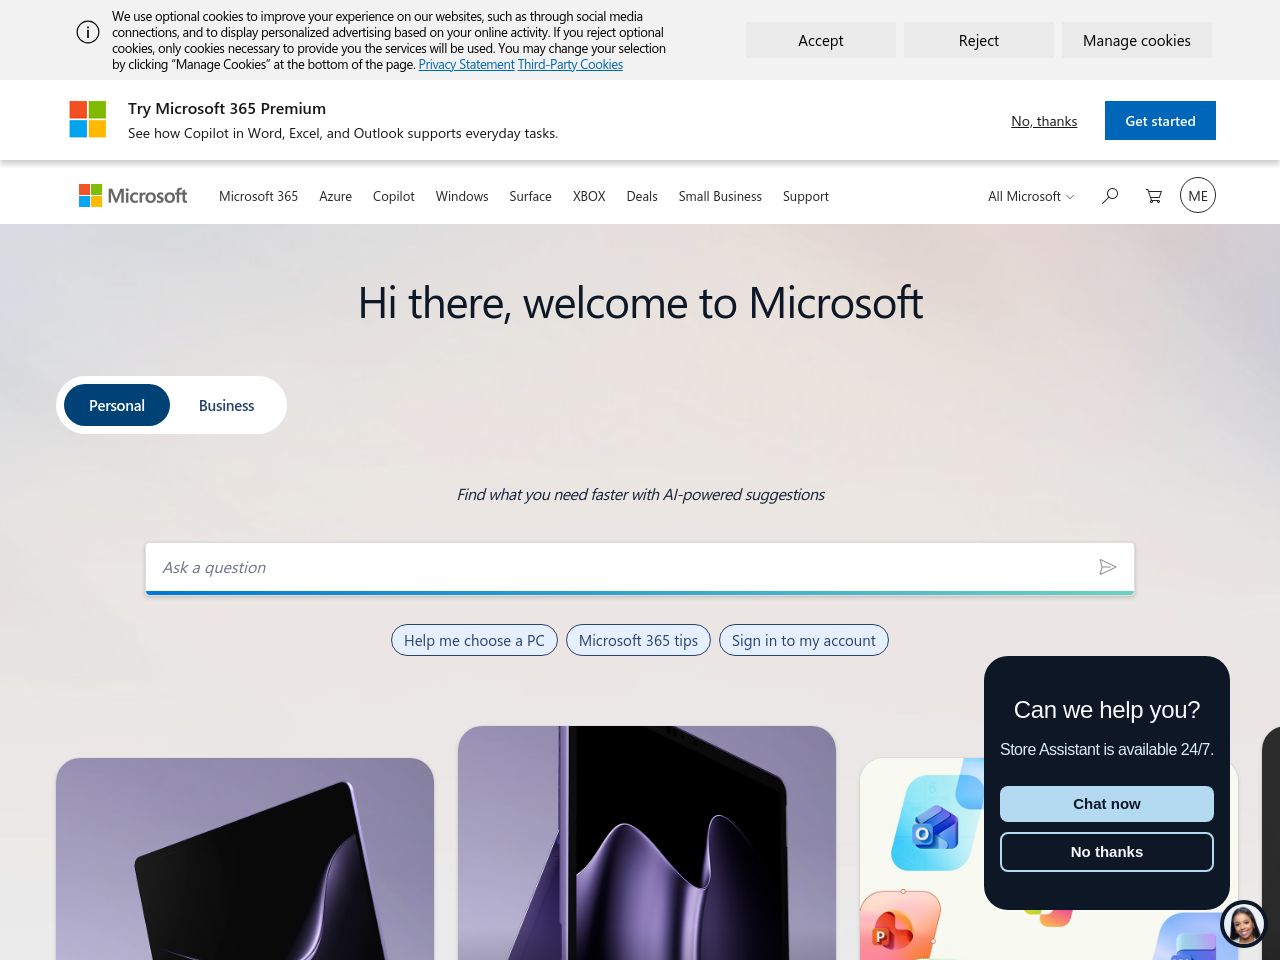
What's new | Developer & IT | Can we help you?
Person vs AI crawler
Text people see that AI crawlers do not
7 of 31 text blocks on the rendered page are missing from the raw HTML that GPTBot, ClaudeBot and PerplexityBot receive. A few of them:
- “Trace Id is missing Skip to main content We use optional cookies to improve your experience on our websites, such as through social media connections, and to d…”
- “If you reject optional cookies, only cookies necessary to provide you the services will be used.”
- “You may change your selection by clicking “Manage Cookies” at the bottom of the page.”
- “Privacy Statement Third-Party Cookies Accept Reject Manage cookies Try Microsoft 365 Premium See how Copilot in Word, Excel, and Outlook supports everyday task…”
- “Let's chat Can we help you?”
Fix plan
The fixes worth the most points
Ranked by how much each one alone would lift the score, as computed by the engine for this page.
- 01Serve your full content in the initial HTMLdev required+10
- 02Add structured data (JSON-LD) so agents get facts, not guesses1 hr+9
- 03Cut the token cost of reading this pagedev required+8
- 04Give agents concrete facts to cite1 hr+5
- 05Repair the structured data that agents currently discard1 hr+3
How this report was made
One automated scan of https://www.microsoft.com/en-us/ on 3 October 2026, with the same engine (v0.3.0) as the free Siteiz scan. We fetched the page twice: as raw HTML, the way AI crawlers receive it, and rendered in a real browser, the way people see it. Scores are deterministic rules, not an AI opinion. Sites change, so this is a snapshot of that day. Methodology
How does your site compare?
Run the same scan on your own page. Free, about a minute, with your score and the fixes worth the most points.